Monitoring
EDR, XDR and MDR tracked apart
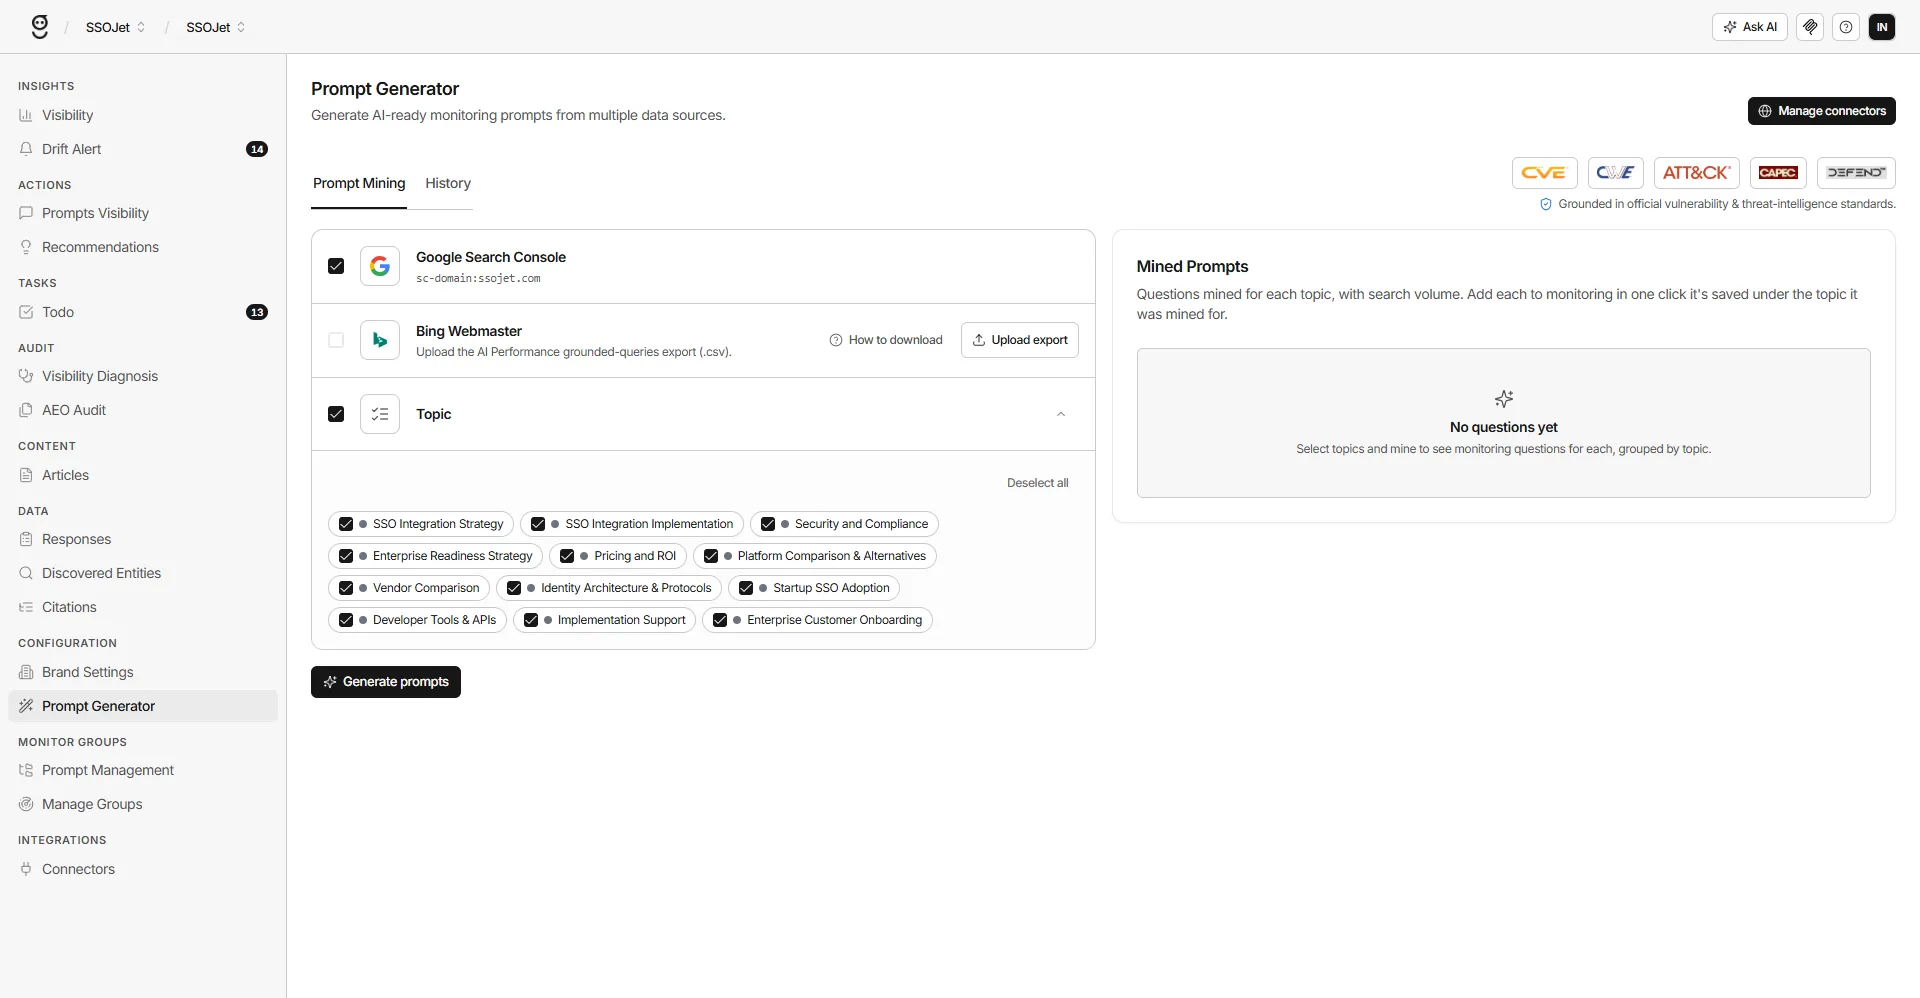
Prompt Topics keeps the three framings separate, so you can see whether the engines put you in the product conversation, the managed one, or neither.
See Prompt Topics →That question is now asked of an assistant before it is asked of a vendor, and the answer decides whether you are in a product conversation or a managed-service one. GrackerAI shows you which of those framings currently name you.
7-day free trial. Cancel anytime before it ends.
The endpoint security AEO reality
EDR, XDR and MDR are three answers to one problem with very different commercial shapes. When an assistant picks a framing for a buyer, it has already narrowed the field — often before anyone has evaluated a detection claim.
Why endpoint buyers research differently
What you get
Prompt Topics keeps the three framings separate, so you can see whether the engines put you in the product conversation, the managed one, or neither.
See Prompt Topics →Brand Sentiment tracks the qualifiers attached to your name, which in this category usually means claims about noise, agent weight or operational burden.
See Brand Sentiment →CVE, CWE, ATT&CK, CAPEC and NIST references on your pages are resolved against the body that issued them, and an active-exploit claim is checked against CISA's Known Exploited Vulnerabilities catalog.
See Security Verification →Identifiers are resolved before a draft is written, and anything the model produced that is not in that resolved set is stripped out before the page publishes.
See Content Engine →New vulnerabilities and security news are swept on a schedule, scored for exploitability and for how closely they touch your products, and the survivors become monitored prompts automatically.
See AI Visibility Monitoring →Prompt coverage
These prompts pull cited sources often, especially where independent test results exist, so weight Perplexity and Claude.
Plays
If the engines only ever name you as a product, you never reach buyers who asked whether to outsource. Track the framings separately and publish for the one you are missing.
Explore Prompt Topics →Independent evaluations get quoted heavily and rarely in full. Citations shows which summaries the engines actually read, so you can see what shaped the sentence about you.
Explore LLM Citations →Platform parity is checked early and models fill gaps with assumptions. An explicit, current coverage page removes an objection you are otherwise losing silently.
Explore Content Engine →Sentiment moves before share of voice. A model that begins hedging about agent overhead is repeating something it read, and that source is findable.
Explore Brand Sentiment →The stack
Find where you are missing today
Understand why a prompt goes to someone else
Turn findings into published pages
Get it live and keep it moving
Questions B2B SaaS teams ask before getting started
The same all 10 AI engines it tracks for every vertical: ChatGPT, Perplexity, Google AI Mode, Google AI Overviews, Gemini, Microsoft Copilot, DeepSeek, Brave Leo, Grok and Claude. Coverage is by plan — 3 engines on Individual, 4 on Team and all 10 on Enterprise.
The EDR, XDR and MDR framings are tracked as separate topics because they lead to different commercial conversations, and sentiment is watched alongside share of voice since operational objections decide this category.
Monitoring starts returning answers on the first run, so you can see where you stand immediately. Movement in citations follows publishing, which depends on how fast you ship the fixes the audit and diagnosis hand you.
No. Classic SEO governs ranking; AEO and GEO govern whether a model quotes you. The technical audit overlaps with an SEO audit in places, but the citation work sits alongside what you already do rather than replacing it.
60 seconds. 7-day free trial, cancel anytime.
Start your 7-day free trial and get your AI Visibility Score in about a minute. See exactly where you stand, where competitors are beating you, and the ranked fixes to get into the answer. Cancel anytime before the trial ends.
7-day free trial. Cancel anytime before it ends. Trusted by 500+ B2B SaaS teams.