Your buyer is a developer, and they are asking the assistant inside the workflow.
AppSec tooling is chosen by the people who have to live with it. They ask Claude and ChatGPT which scanner to put in the pipeline, how noisy it is and whether it will block a merge. GrackerAI shows you which of those answers name you.
The tool that wins is the one developers do not route around.
AppSec adoption is decided by friction, not by detection tables. Assistants answer that way too — with pipeline fit, signal quality and time cost — which makes the prompts that decide your category quite different from the ones a security marketer would expect.
Why AppSec buyers research differently
Pipeline fit is the first questionWhether it blocks a merge matters more than what it can detect
False positives are the deciding objectionSignal quality is raised earlier and more often than coverage
Open source sets the baselineEvery commercial tool is compared against a free one that is already installed
Scan time is a real constraintA scanner that adds ten minutes to CI gets disabled, not evaluated
What you get
What the platform does when the buyer writes the code
Monitoring
Pipeline-shaped prompt coverage
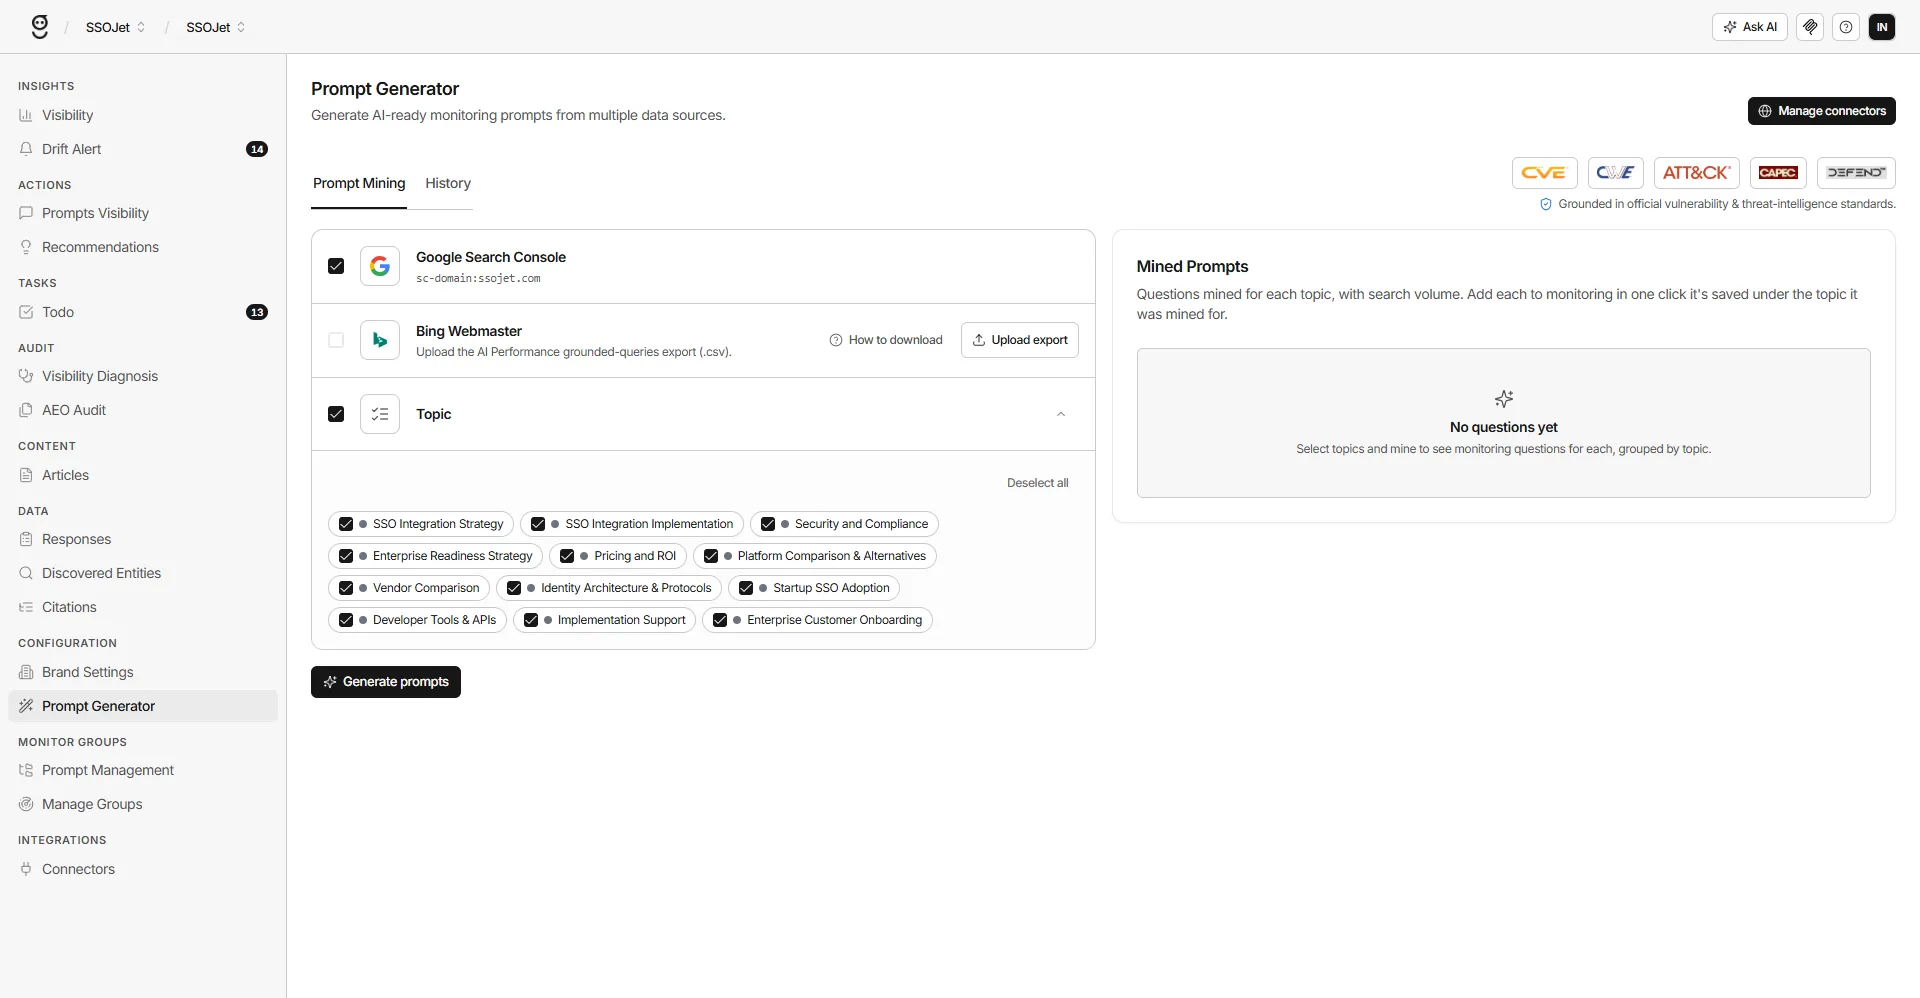
Prompt Mining builds monitors from implementation questions — how a scanner behaves in CI, what it does to build time, how noisy it is — rather than the category headlines that never decide an AppSec purchase.
The Technical AEO Audit fetches your documentation before JavaScript runs, so you learn whether the integration guide developers rely on is actually extractable or merely looks complete in a browser.
CVE, CWE, ATT&CK, CAPEC and NIST references on your pages are resolved against the body that issued them, and an active-exploit claim is checked against CISA's Known Exploited Vulnerabilities catalog.
Identifiers are resolved before a draft is written, and anything the model produced that is not in that resolved set is stripped out before the page publishes.
New vulnerabilities and security news are swept on a schedule, scored for exploitability and for how closely they touch your products, and the survivors become monitored prompts automatically.
Developer-shaped security prompts land hardest on Claude, with Perplexity close behind on comparison questions.
Prompt category · example query · where it lands most
Pipeline“SAST that runs in CI without blocking every merge”ClaudeChatGPT
Signal“Which SCA tools have the fewest false positives”PerplexityClaude
Open source“Is a commercial DAST worth it over ZAP”ClaudePerplexity
Coverage“Scanning a monorepo with mixed languages”ClaudeChatGPT
Runtime“WAF or RASP for an API-heavy application”PerplexityClaude
Plays
Four plays that move AppSec pipelines
01
Answer the friction question first
Developers ask what a scanner costs them in time and noise before they ask what it finds. Those prompts decide the category and are almost never the ones on a security content calendar.
Engines quote documentation more readily than product pages, but only when it parses. Run the audit across your docs so the integration guide you already wrote is available to be cited.
Every evaluation includes a free alternative that is already installed. If the engines answer that comparison without you, they answer it against you. Find those prompts and publish the honest version.
AppSec content is dense with CWE and CVE identifiers. Verification resolves each one against MITRE so a page about finding vulnerabilities does not itself contain an invented one.
Questions B2B SaaS teams ask before getting started
The same all 10 AI engines it tracks for every vertical: ChatGPT, Perplexity, Google AI Mode, Google AI Overviews, Gemini, Microsoft Copilot, DeepSeek, Brave Leo, Grok and Claude. Coverage is by plan — 3 engines on Individual, 4 on Team and all 10 on Enterprise.
Monitors are built from pipeline and signal-quality questions rather than detection-coverage headlines, the audit is run against documentation where developers read, and CWE and CVE references are resolved against MITRE before anything publishes.
Monitoring starts returning answers on the first run, so you can see where you stand immediately. Movement in citations follows publishing, which depends on how fast you ship the fixes the audit and diagnosis hand you.
No. Classic SEO governs ranking; AEO and GEO govern whether a model quotes you. The technical audit overlaps with an SEO audit in places, but the citation work sits alongside what you already do rather than replacing it.
Start your 7-day free trial and get your AI Visibility Score in about a minute. See exactly where you stand, where competitors are beating you, and the ranked fixes to get into the answer. Cancel anytime before the trial ends.